Reinforcement Learning for Solving Multimodal Functions with CMA-ES
Marc Oedingen, Oskar Girardin, Nikolaus Hansen, and Alexandre Chotard
In Parallel Problem Solving from Nature – PPSN XIX, Trento, Italy, 2027
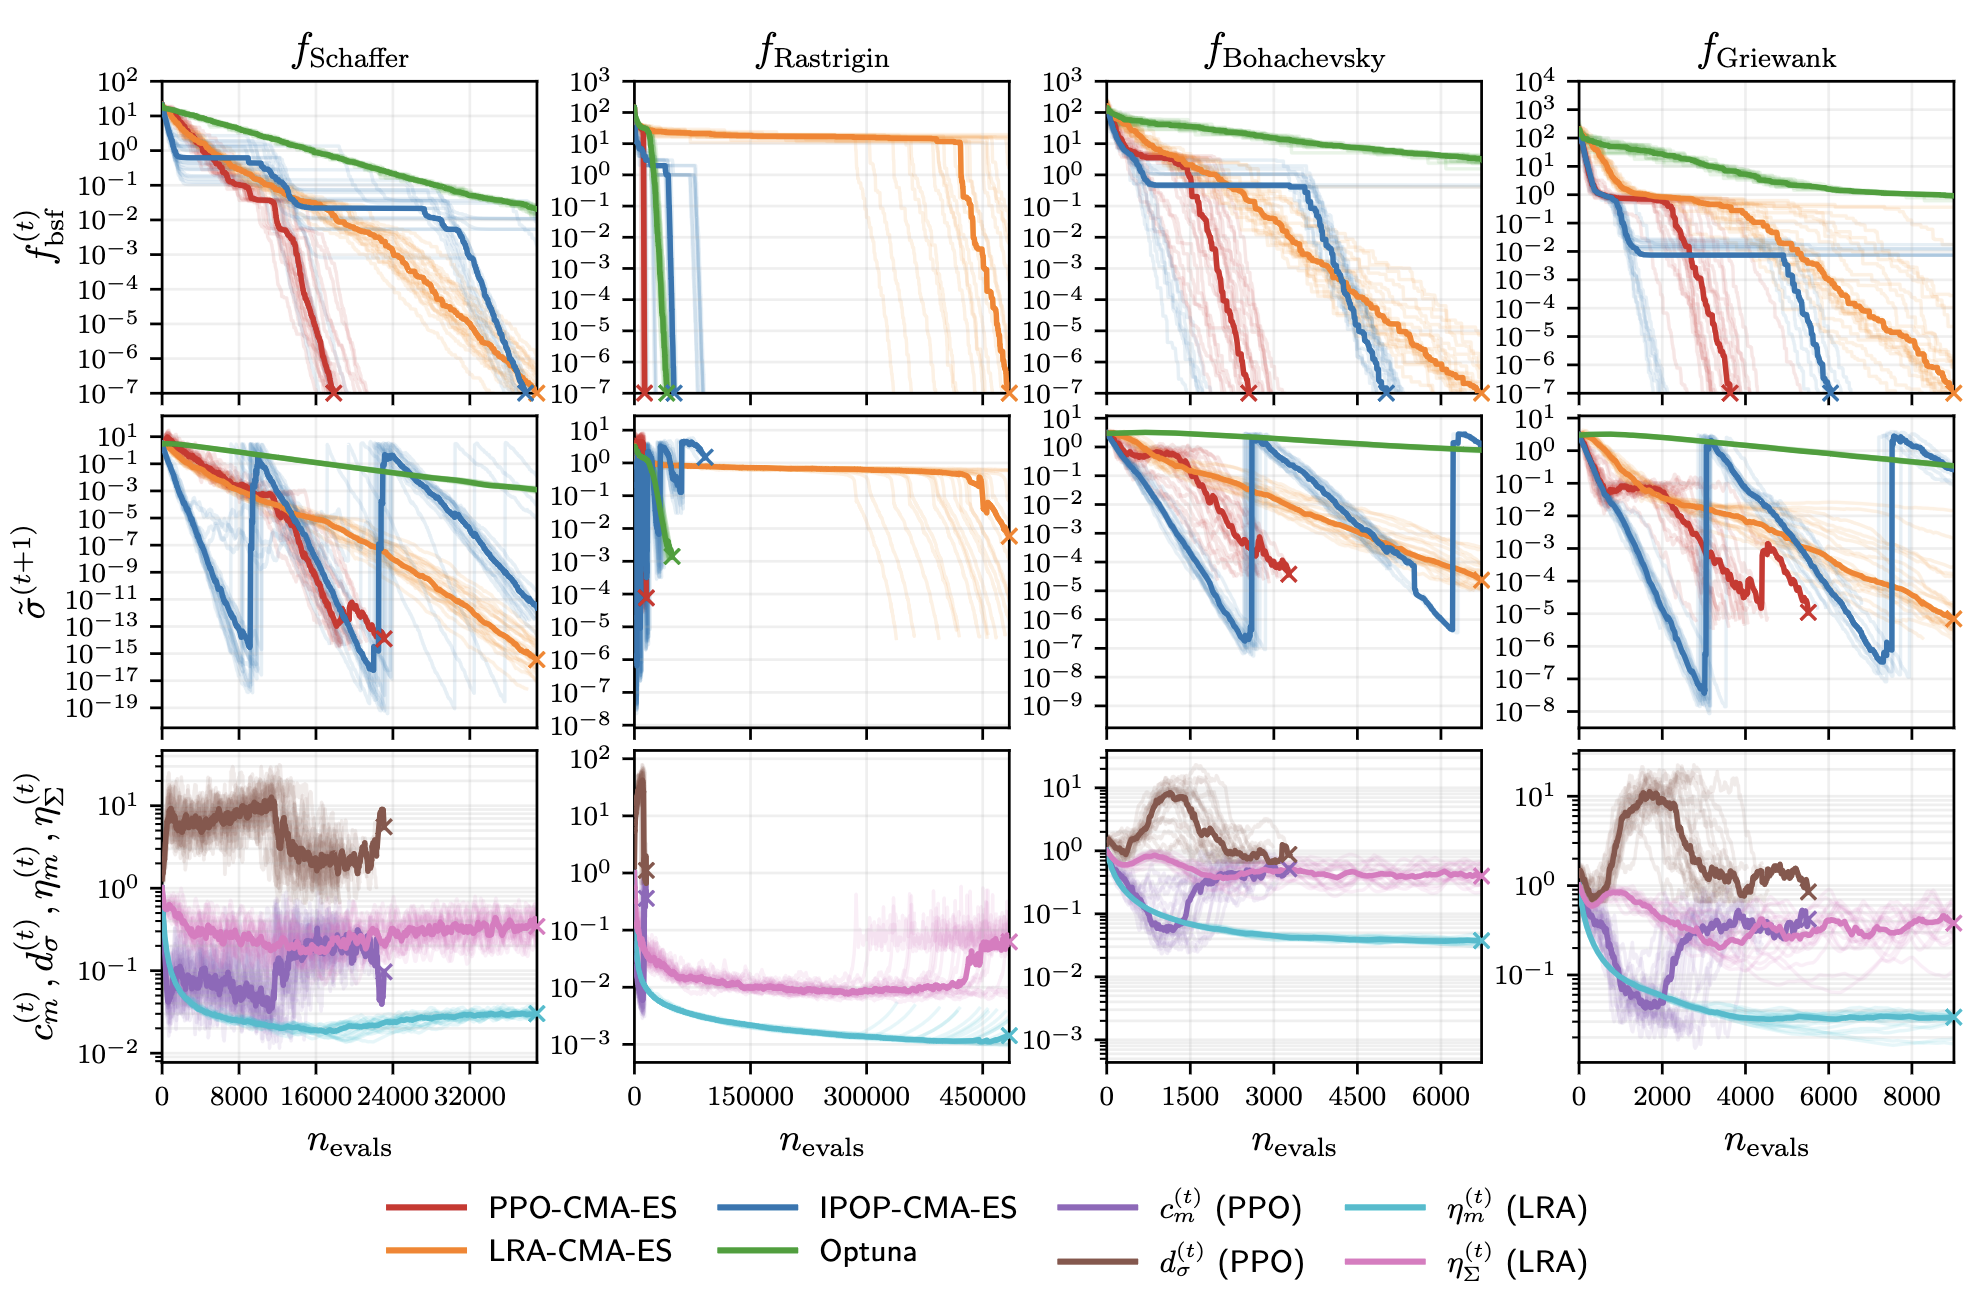
In this paper, we investigate dynamic meta-parameter control for the covariance matrix adaptation evolution strategy (CMA-ES) through deep reinforcement learning (DRL). We formalize the online adaptation of meta-parameters as a Markov decision process (MDP), where each iteration corresponds to one decision step. Based on this formalization, we integrate a controller designed with proximal policy optimization (PPO) into CMA-ES that adapts the learning rate of the mean and the damping parameter of cumulative step-size adaptation (CSA) during the optimization run. Importantly, the controller preserves all known invariance properties of CMA-ES. We train the PPO model only on the Rastrigin function. The learned controller enables CMA-ES with default population size to solve a variety of multimodal functions: on the Rastrigin function, the PPO-CMA-ES is four times faster than IPOP-CMA-ES, and it is also highly competitive on a variety of other multimodal functions, while maintaining reasonable performance on unimodal functions.
 Reinforcement Learning for Solving Multimodal Functions with CMA-ESIn Parallel Problem Solving from Nature – PPSN XIX, Trento, Italy, 2027


